An SEO MCP server that sees pages as AI crawlers do.
CrawlView is an SEO MCP server: it fetches a public page and reports what search engines and AI crawlers read from it, from titles, headings and canonical tags to structured data, links and sitemaps. Its AI crawler checker reads robots.txt for 18 search and AI crawlers, so you know whether ChatGPT, Claude, Perplexity and Google can read a page before you wonder why it is never cited.
01See it work
CrawlView, in real use.
5 screens from real calls to CrawlView. Every value shown is what the tool returned; click a screen to open it full size.
02How it works
One question, four reads of the page.
You ask in plain words. Your assistant calls CrawlView, which fetches what a crawler would fetch, without running scripts, and answers with exact values instead of a guess.
- 01You askCan ChatGPT read our pricing page?
- 02Your assistant calls CrawlViewIt picks the tool that fits the question.
check_ai_access - 03CrawlView reads the siterobots.txt, the page, llms.txt and the sitemap, from a public address, as a crawler would.
- 04An exact answerEach crawler allowed or blocked, with the robots.txt rule that decided it.
03AI crawlers
GPTBot, ClaudeBot and 16 other crawlers.
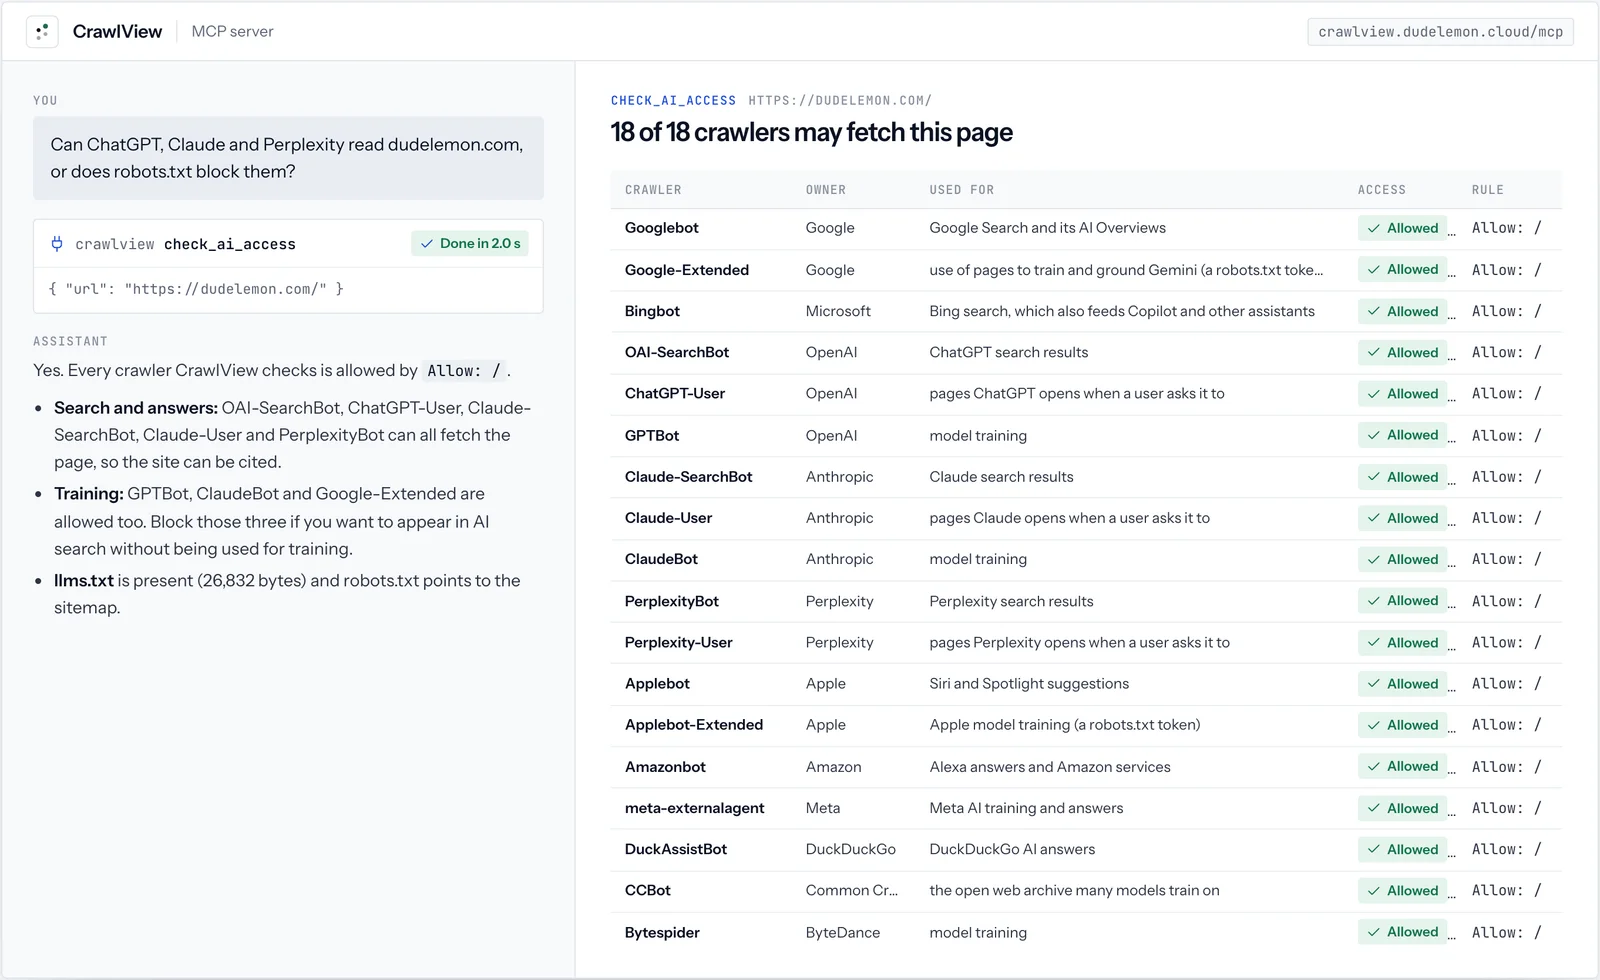
AI crawlers do different jobs. Search crawlers fetch a page so an assistant can cite it in an answer; training crawlers collect pages to train models. Blocking one does not block the other, so check_ai_access reports each by name.
| Crawler | Company | What it fetches pages for | Kind |
|---|---|---|---|
| Googlebot | Google Search and its AI Overviews | Search | |
| Google-Extended | Using pages to train and ground Gemini (a robots.txt token, not a separate crawler) | Training | |
| Bingbot | Microsoft | Bing search, which also feeds Copilot and other assistants | Search |
| OAI-SearchBot | OpenAI | ChatGPT search results | Search |
| ChatGPT-User | OpenAI | Pages ChatGPT opens when a user asks it to | On request |
| GPTBot | OpenAI | Model training | Training |
| Claude-SearchBot | Anthropic | Claude search results | Search |
| Claude-User | Anthropic | Pages Claude opens when a user asks it to | On request |
| ClaudeBot | Anthropic | Model training | Training |
| PerplexityBot | Perplexity | Perplexity search results | Search |
| Perplexity-User | Perplexity | Pages Perplexity opens when a user asks it to | On request |
| Applebot | Apple | Siri and Spotlight suggestions | Search |
| Applebot-Extended | Apple | Apple model training (a robots.txt token) | Training |
| Amazonbot | Amazon | Alexa answers and Amazon services | Answers |
| meta-externalagent | Meta | Meta AI training and answers | Training |
| DuckAssistBot | DuckDuckGo | DuckDuckGo AI answers | Answers |
| CCBot | Common Crawl | The open web archive many models train on | Training |
| Bytespider | ByteDance | Model training | Training |
04robots.txt
robots.txt examples for AI crawlers.
Three common policies. CrawlView reads robots.txt as RFC 9309 defines it: the most specific user agent group applies, the longest matching rule wins, and allow wins a tie. Paste a draft into a staging page and check it before you publish.
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
User-agent: CCBot
Disallow: /

User-agent: *
Allow: /User-agent: *
Disallow: /drafts/
Allow: /
Sitemap: https://example.com/sitemap.xmlUser-agent: Bytespider
Disallow: /
User-agent: *
Allow: /Two details catch people out. Google-Extended and Applebot-Extended are tokens, not crawlers: Googlebot still fetches the page for Search, and the token only decides whether Google may use it for Gemini. And a robots.txt that answers with a server error is read as blocking the whole site, so a broken robots.txt can take a site out of AI answers without anyone noticing. CrawlView reports both.
05Page audit
What inspect_page checks, and the limits it uses.
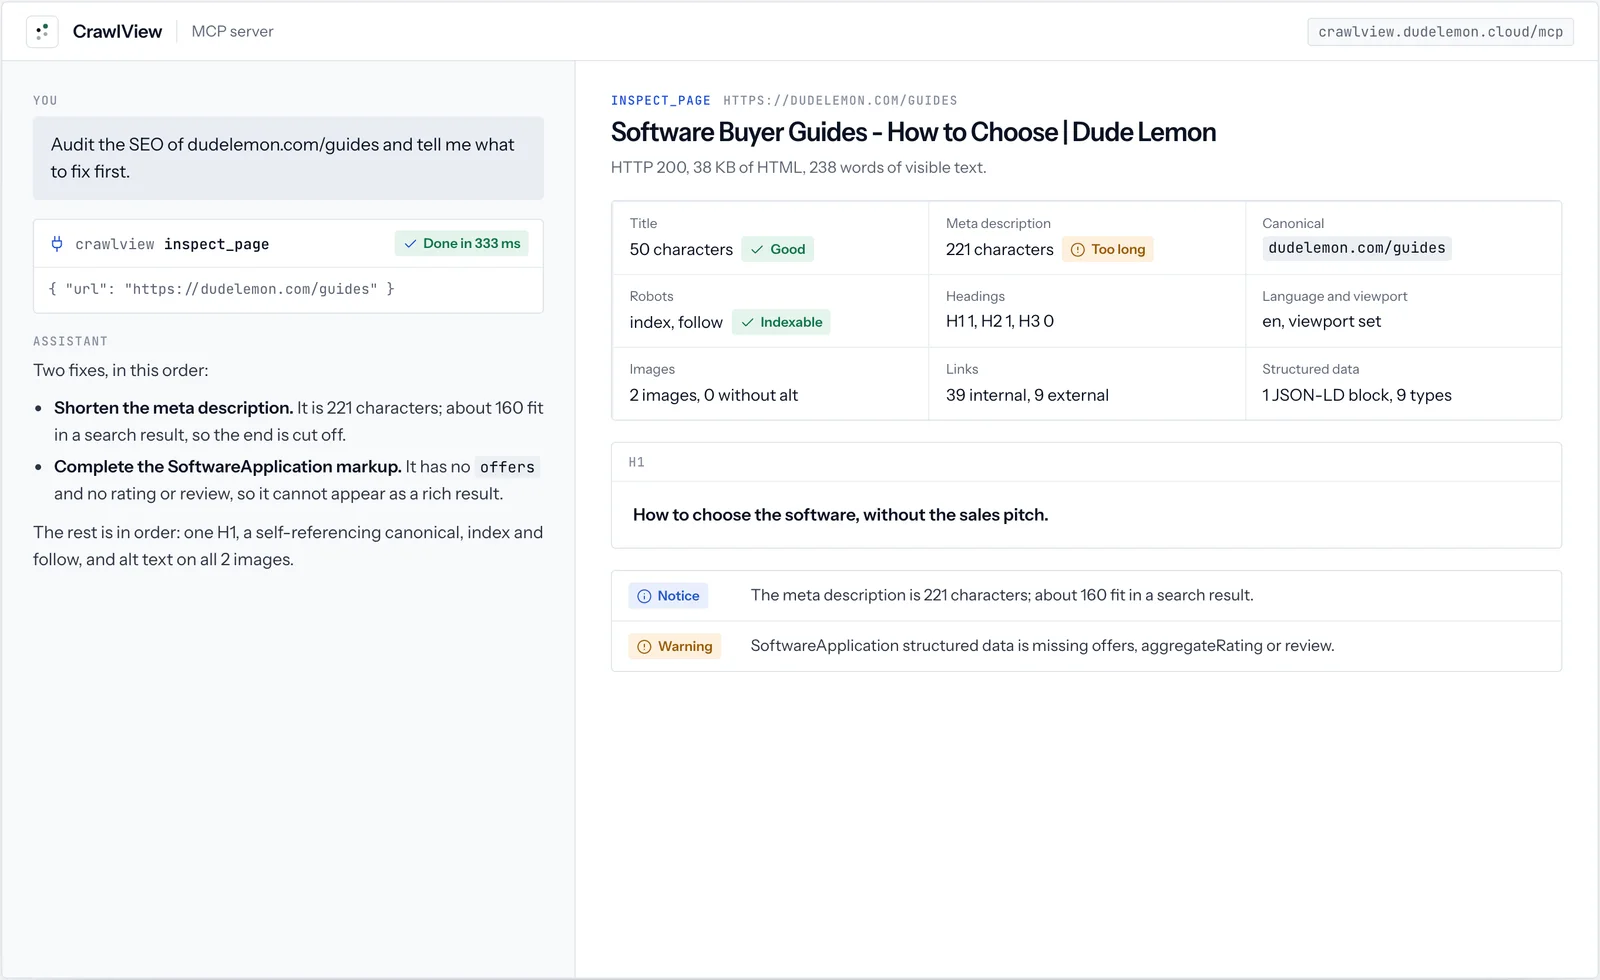
inspect_page reads one page and returns its signals with a ranked list of issues. These are the checks and the points at which it raises them.
| Signal | What CrawlView reports | Raises an issue when |
|---|---|---|
| Status and redirects | The final address, the HTTP status and every redirect on the way | The page answers 400 or above |
| Title | The text and its length | It is missing, over 60 characters or under 15 |
| Meta description | The text and its length | It is missing, over 160 characters or under 70 |
| Canonical | The canonical address | It is missing or points to a different page |
| Robots meta and X-Robots-Tag | Both values and whether the page can be indexed | Either says noindex |
| Headings | H1 to H6 counts and the H1, H2 and H3 text | There is no H1, or more than one |
| Images | How many images, and how many have no alt attribute | Any image has no alt attribute |
| Open Graph | og:title, og:description, og:image and the Twitter card | There is no og:image |
| Structured data | JSON-LD blocks and their types | A block is not valid JSON, or a type misses a required property |
| Text | Words of visible text | There are fewer than 200 |
06Install
Install CrawlView.
CrawlView runs on our servers, so there is nothing to download. Add its address to your assistant, and its 5 tools appear the next time you start a conversation.
claude mcp add --transport http crawlview https://crawlview.dudelemon.cloud/mcpRun in your terminal. Add --scope user to make it available in every project.
07Tools
Its tools, and what each returns.
inspect_page- Status, redirects, title and description lengths, canonical, robots and X-Robots-Tag, headings, Open Graph, alt text coverage, links, word count, and a ranked list of issues.
check_ai_access- Whether Googlebot, Bingbot, GPTBot, OAI-SearchBot, ClaudeBot, Claude-SearchBot, PerplexityBot, Google-Extended and ten more may fetch the page, with the exact robots.txt rule, plus llms.txt.
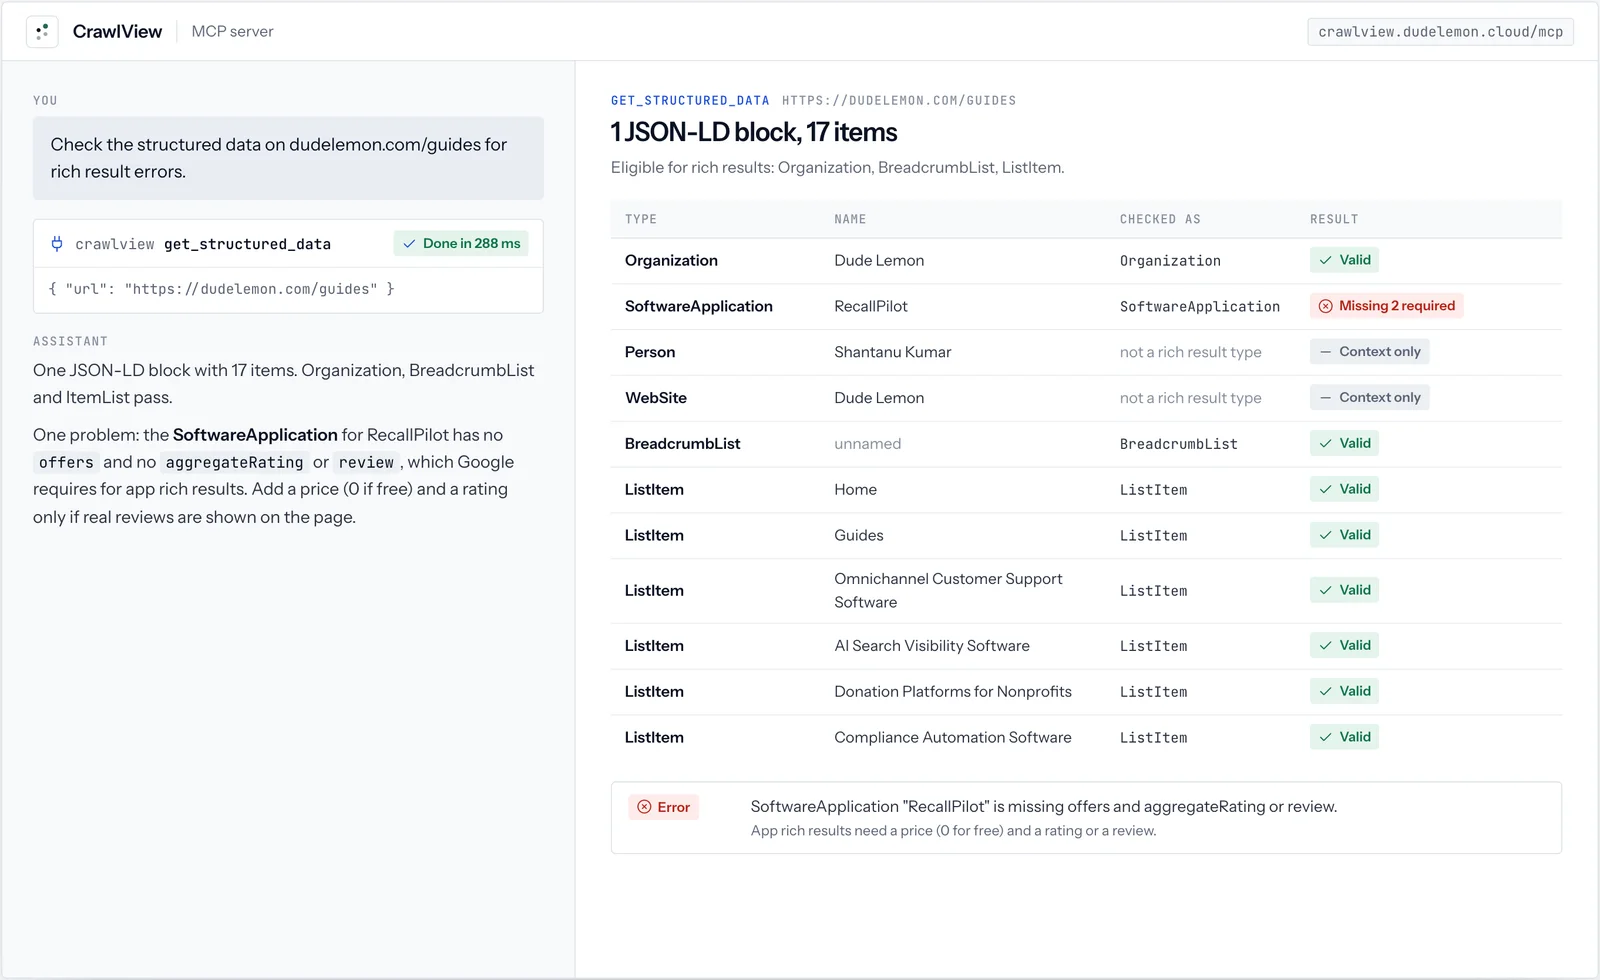
get_structured_data- Every JSON-LD block, flattened and checked against the properties Google requires for rich results.
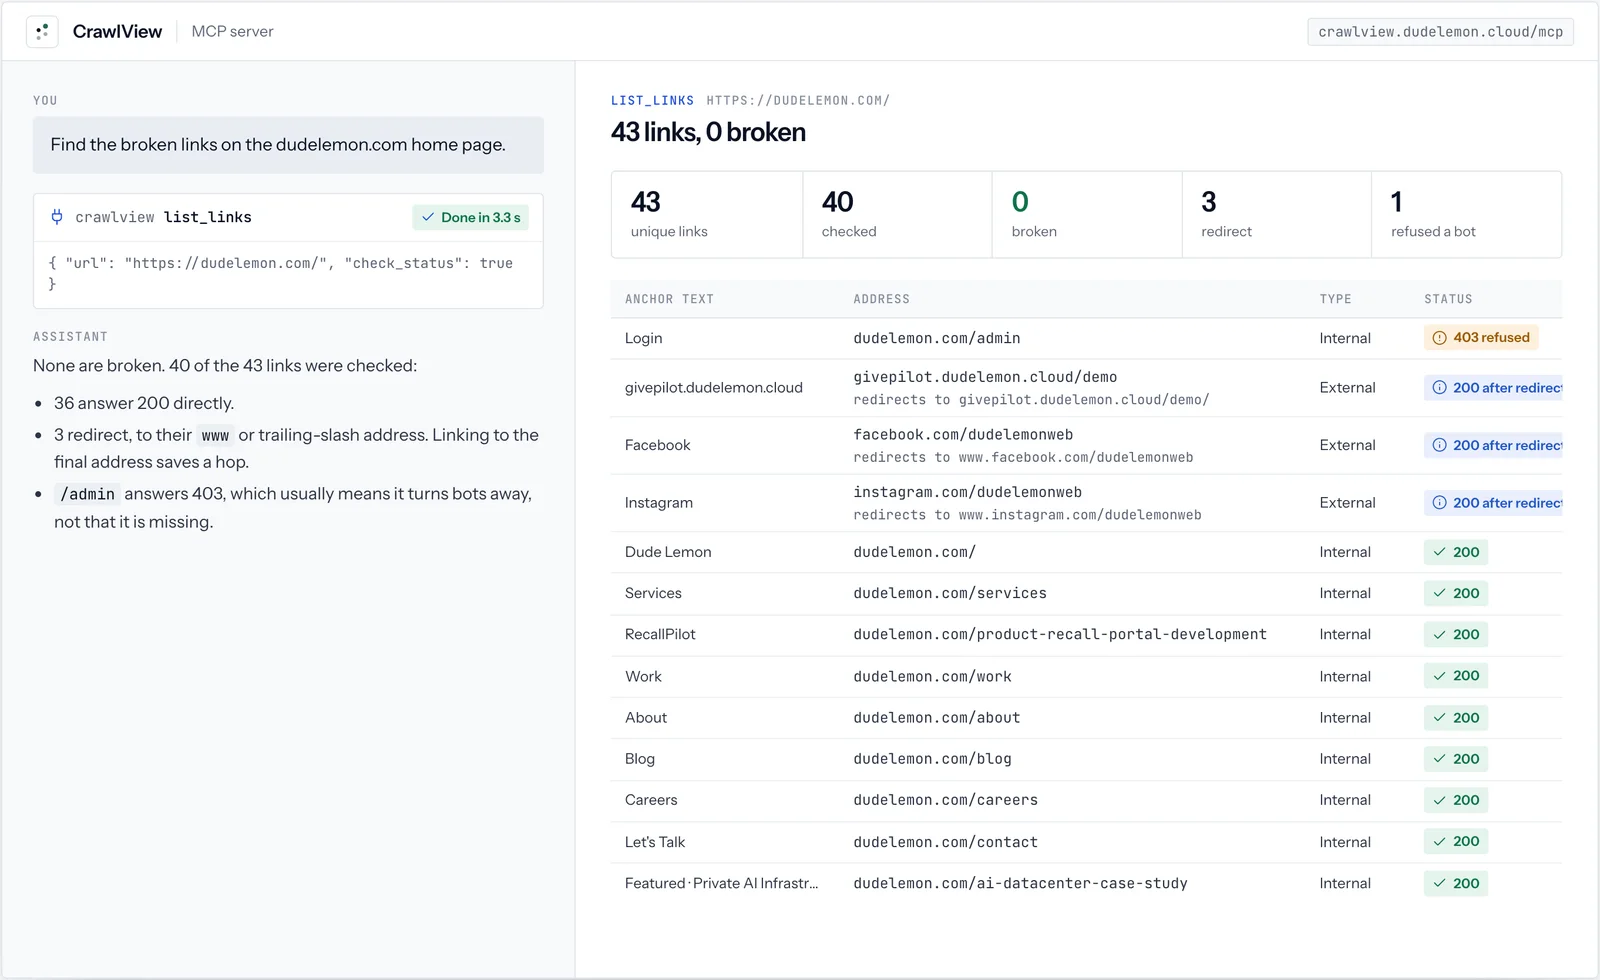
list_links- Unique links with anchor text and rel attributes, and the HTTP status of up to 40 of them.
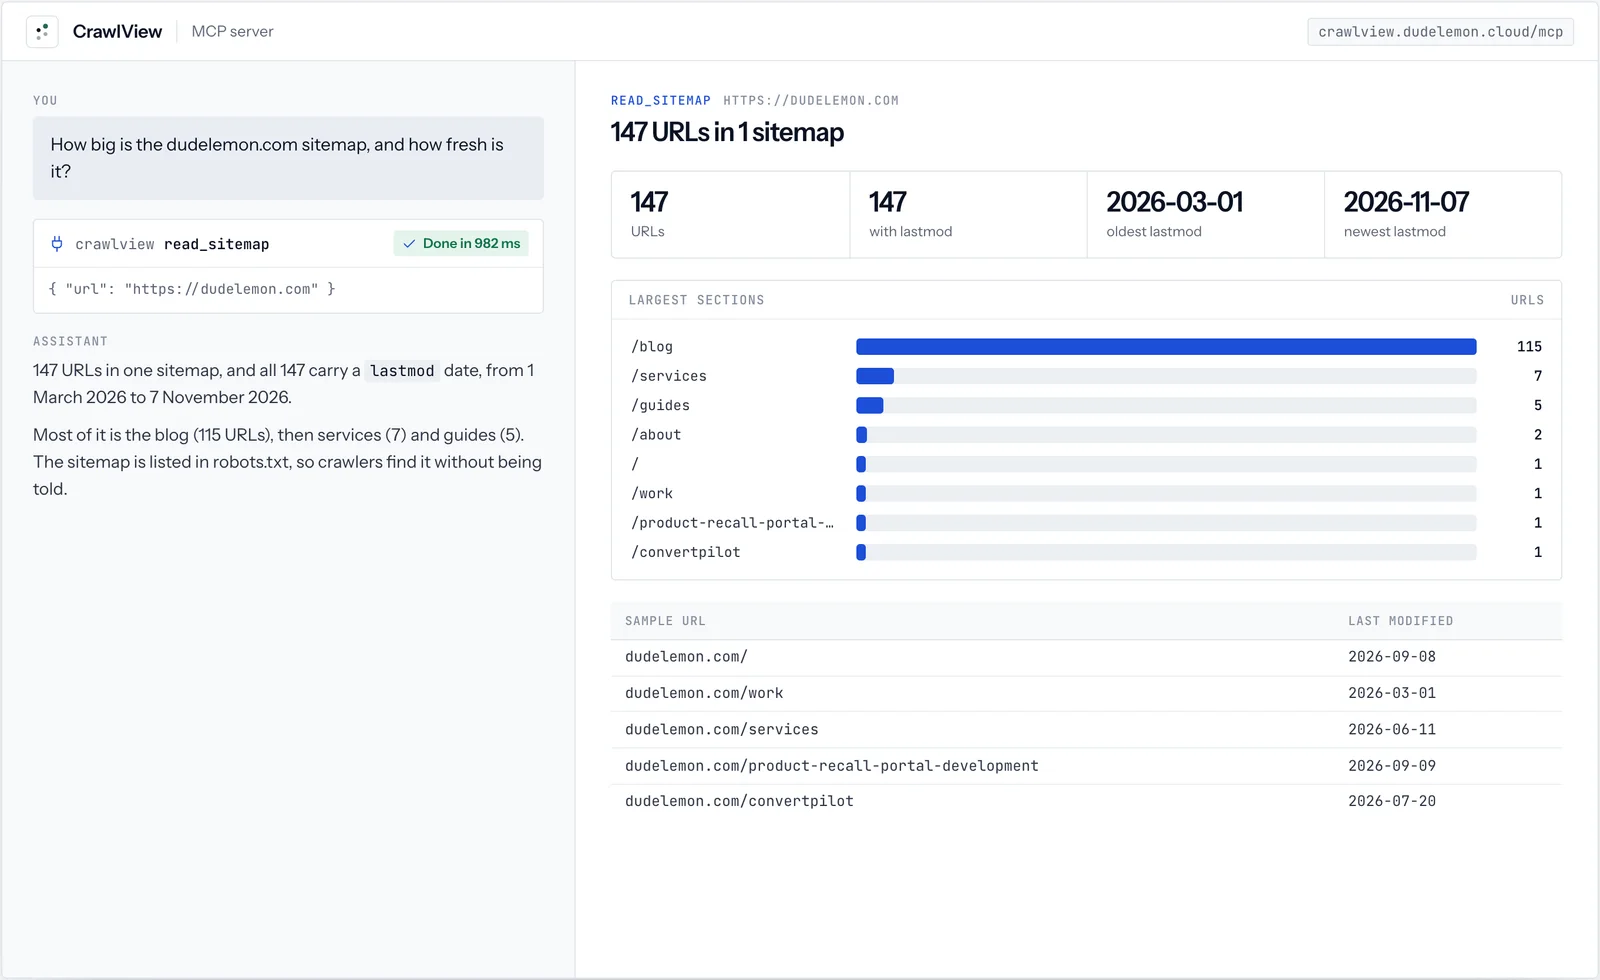
read_sitemap- Sitemaps from robots.txt or /sitemap.xml: URL count, lastmod range, largest sections and a sample.
08Ask in your own words
Say what you need. CrawlView does the exact part.
You do not call CrawlView’s tools by name. Ask your assistant, and it calls them when the question needs live, exact data.
- Audit the SEO of https://example.com/pricing and tell me what to fix first.
- Can ChatGPT and Claude read our blog, or does robots.txt block them?
- Check the structured data on this product page for rich result errors.
- Find the broken links on our home page.
09Works well with
Related tools.
FAQ
CrawlView, answered
Anything we have not answered here, ask us directly. A senior engineer replies.
Does CrawlView run JavaScript?
No. It reads the HTML the server returns, as most AI crawlers do. Content that only appears after scripts run in a browser is invisible to it, and usually to those crawlers too.
Which crawlers does check_ai_access cover?
Googlebot, Google-Extended, Bingbot, OAI-SearchBot, ChatGPT-User, GPTBot, Claude-SearchBot, Claude-User, ClaudeBot, PerplexityBot, Perplexity-User, Applebot, Applebot-Extended, Amazonbot, meta-externalagent, DuckAssistBot, CCBot and Bytespider.
How is robots.txt interpreted?
As RFC 9309 defines it: the most specific user agent group applies, the longest matching rule wins, allow wins a tie, and wildcards and end anchors are honoured. A robots.txt that cannot be read because of a server error is treated as blocking everything, as the standard requires.
Is CrawlView free?
Yes. CrawlView is free and needs no account or API key.
How do I install CrawlView?
Add https://crawlview.dudelemon.cloud/mcp to your assistant as a remote MCP server. In Claude Code run claude mcp add --transport http crawlview https://crawlview.dudelemon.cloud/mcp; in the Claude apps add it as a custom connector with no sign-in; in Cursor or VS Code add it to mcp.json.
Does blocking GPTBot remove my site from ChatGPT search?
No. ChatGPT search uses OAI-SearchBot, and pages a user asks ChatGPT to open use ChatGPT-User. GPTBot collects pages for training. You can block GPTBot and stay in ChatGPT search.
Can CrawlView check a page on my laptop or intranet?
No. It only fetches public addresses, and refuses private and internal networks. Publish to a public staging address to check a draft.